 FREE
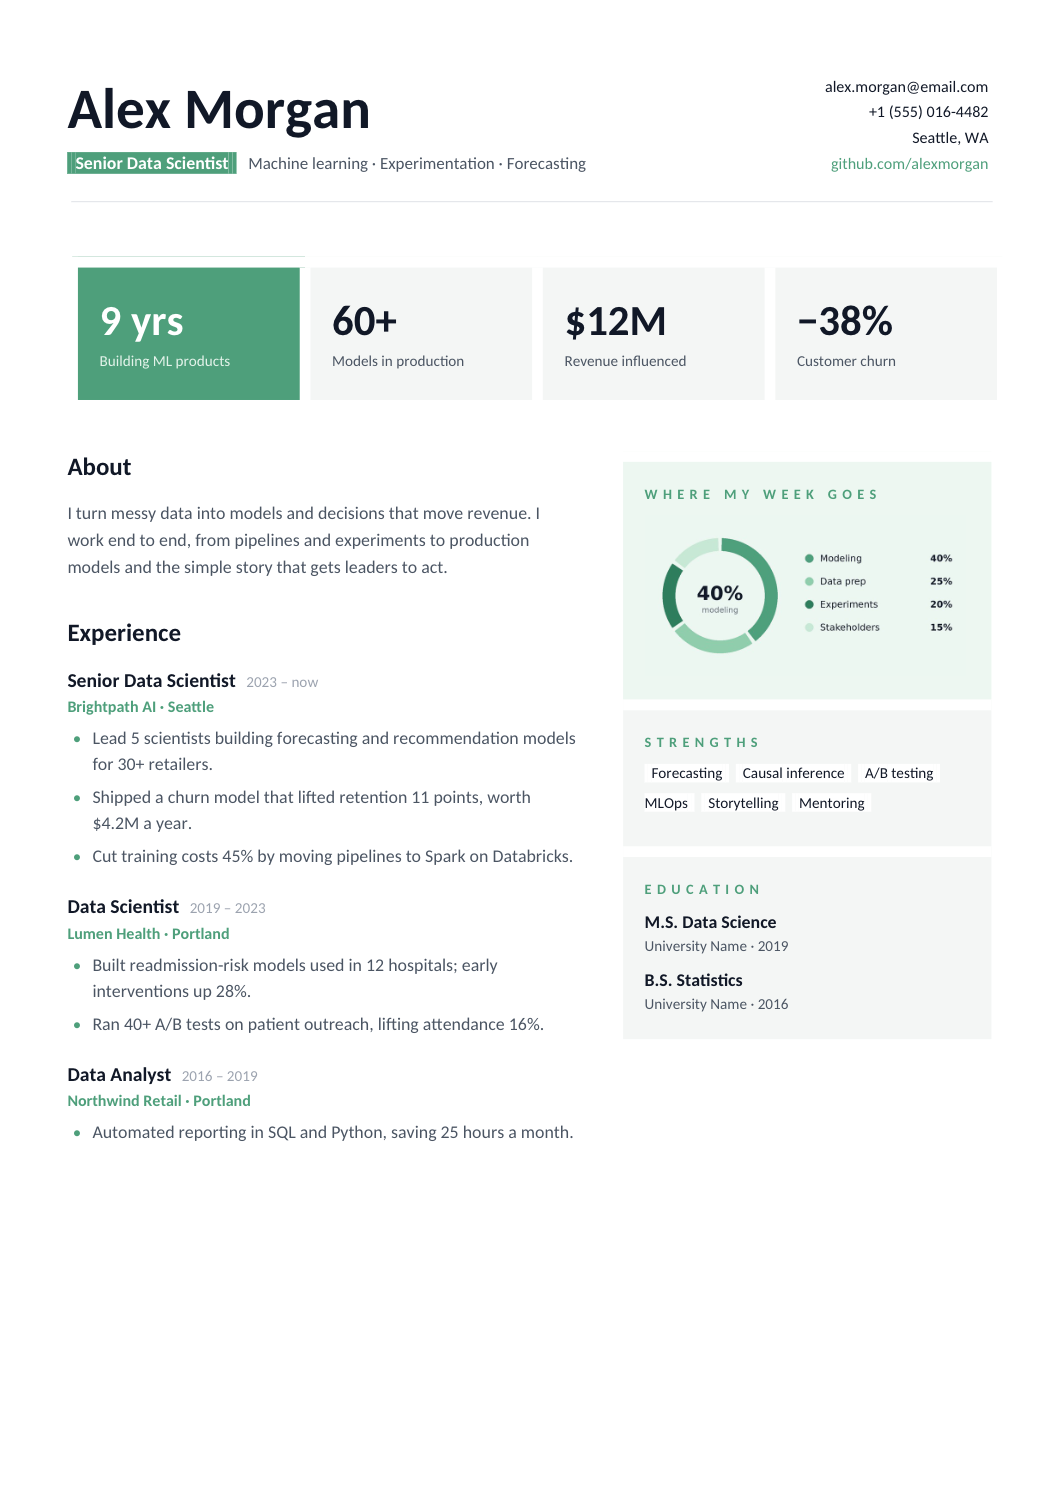
Data Scientist Resume
A resume for data scientists who build models and run experiments, with a tools block for languages, libraries and platforms and experience bullets that measure impact in business terms.
 FREE
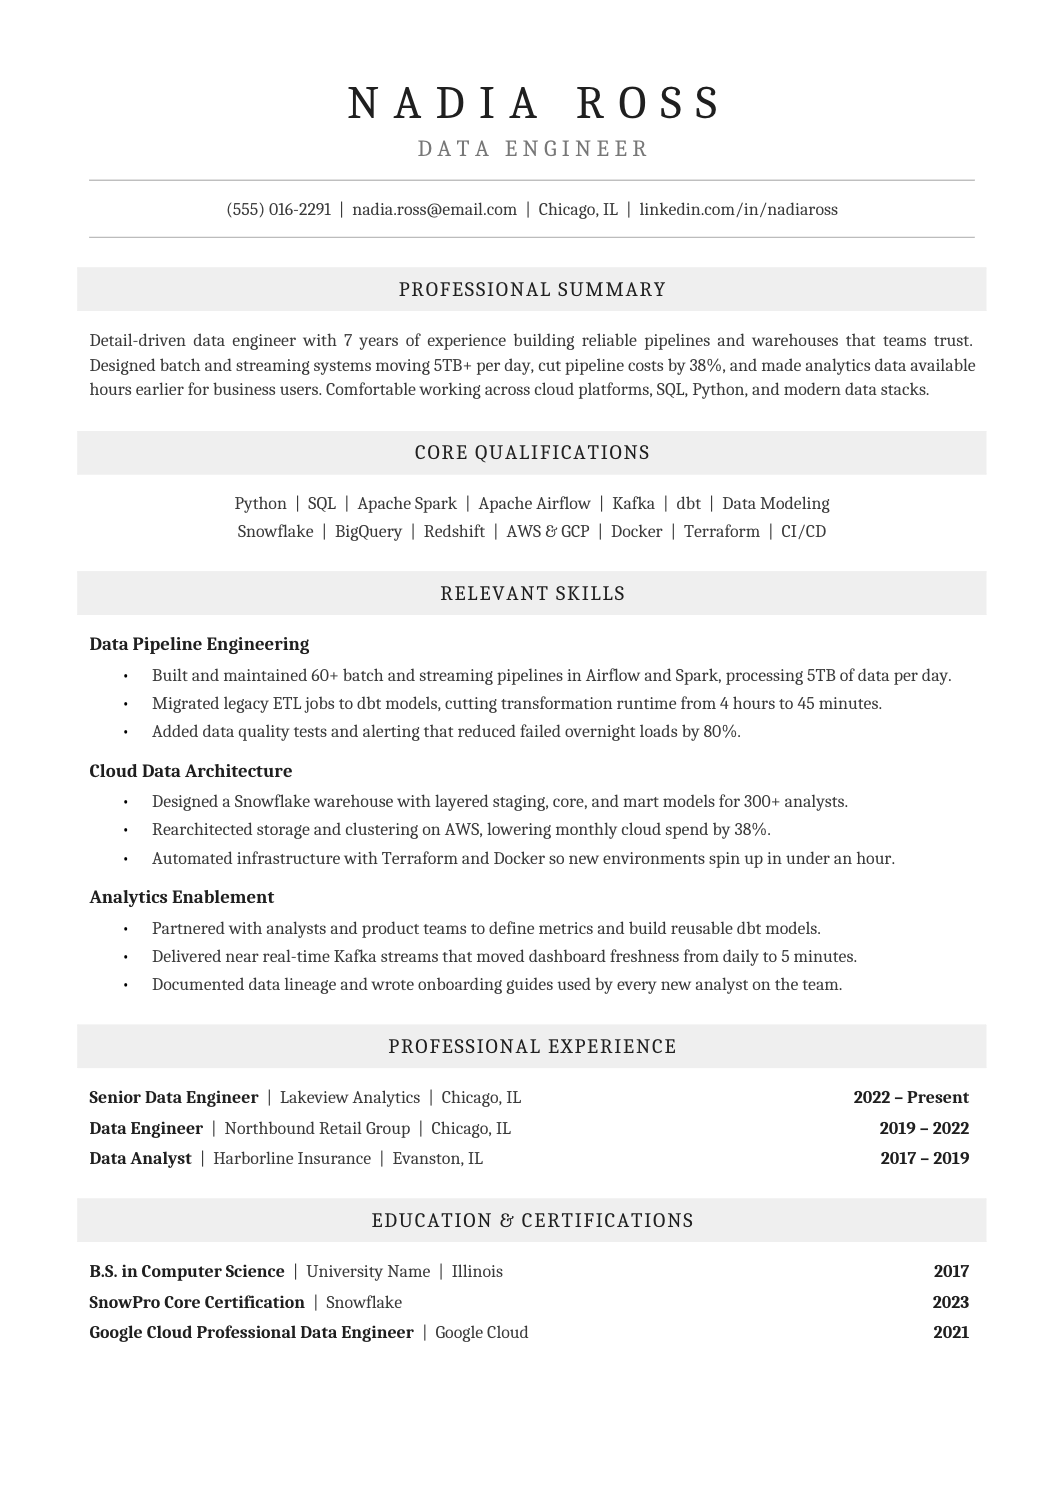
One-page A4 preview. Cambria typography, gray section bands, and a one-column layout.
A resume for engineers who build the pipelines and platforms analysts and scientists depend on. The skills block covers languages, orchestration, warehouses, streaming and cloud, and the bullets are about scale, freshness and reliability.
The sample is a data engineer on a Spark, Airflow and Snowflake stack in AWS. Replace it with your own platform.
Data engineering has clear numbers: rows or terabytes processed, pipeline latency, job failure rate, warehouse cost, time saved for downstream teams. 'Rebuilt the nightly ETL in Airflow and Spark, cutting run time from six hours to 50 minutes and reducing failed runs 90%' is the pattern. Mention data modelling and quality work too; it's often what separates candidates. If your background is application development, the Backend Developer Resume and Python Developer Resume show the parallel structure. Analytics-side roles are covered by the Business Intelligence Analyst Resume, and modelling roles by the Data Scientist Resume.
Name the cloud platform and its data services precisely; certifications (AWS Data Engineer, GCP Professional Data Engineer, Databricks) go in a short section. The layout stays single-column for portal parsing. Infrastructure-heavy data roles may also want to compare the Cloud Engineer Resume.
FREEA resume for data scientists who build models and run experiments, with a tools block for languages, libraries and platforms and experience bullets that measure impact in business terms.
 FREE
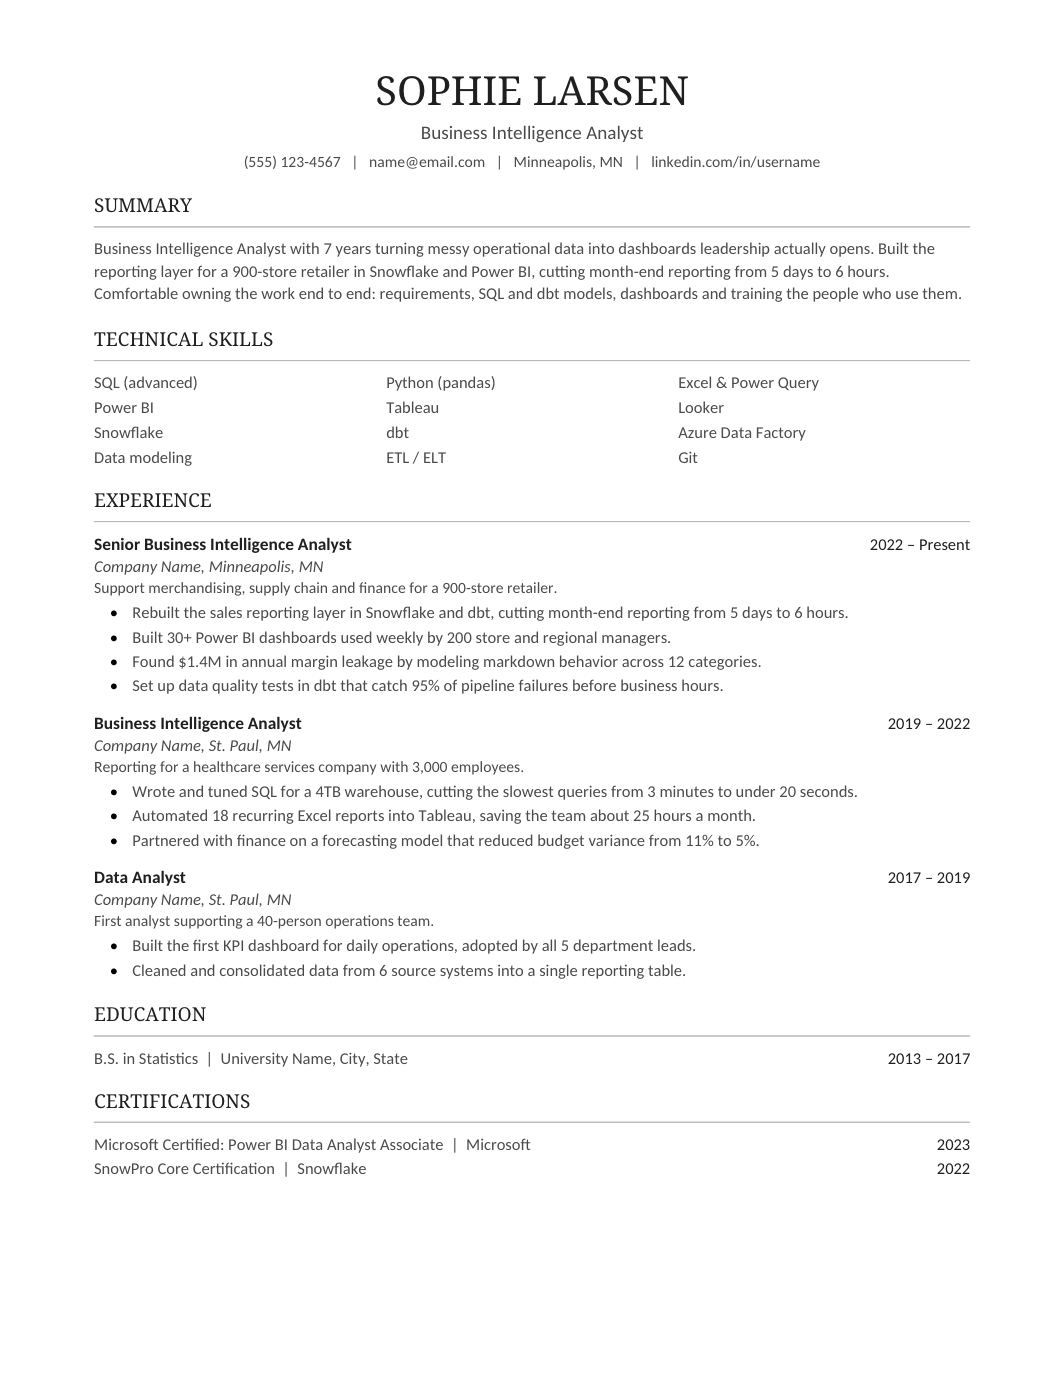
A resume for analysts who build reporting and dashboards for business teams.
 FREE
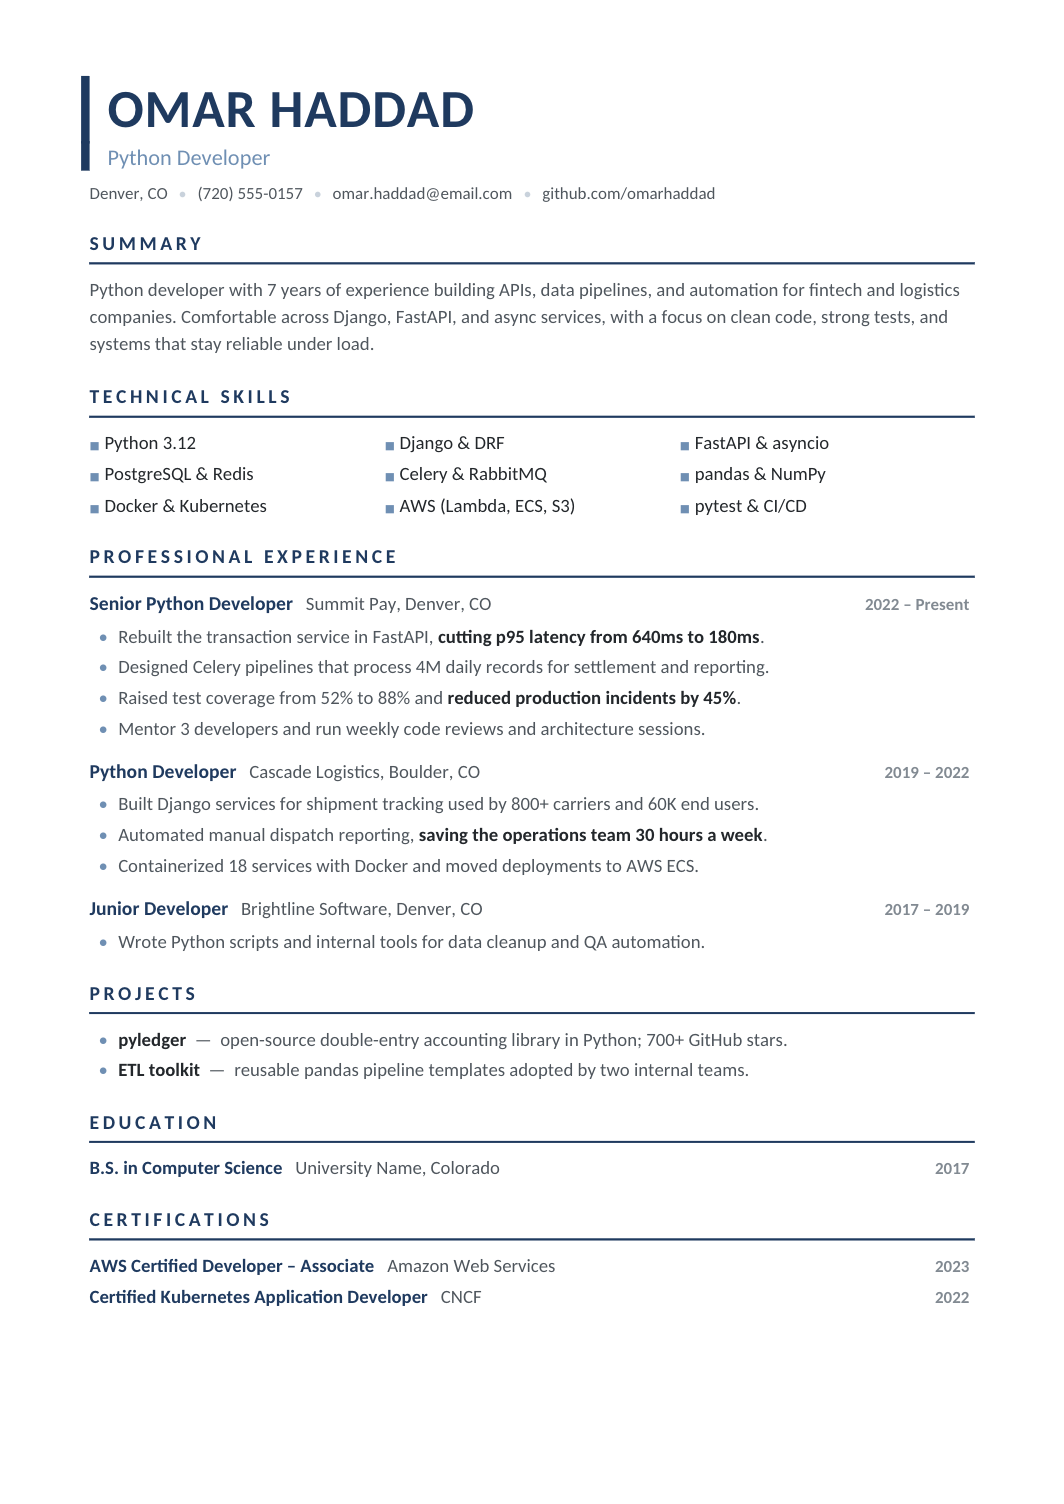
A resume for developers working mainly in Python, whether that's web backends, automation, data pipelines or tooling.
 FREE
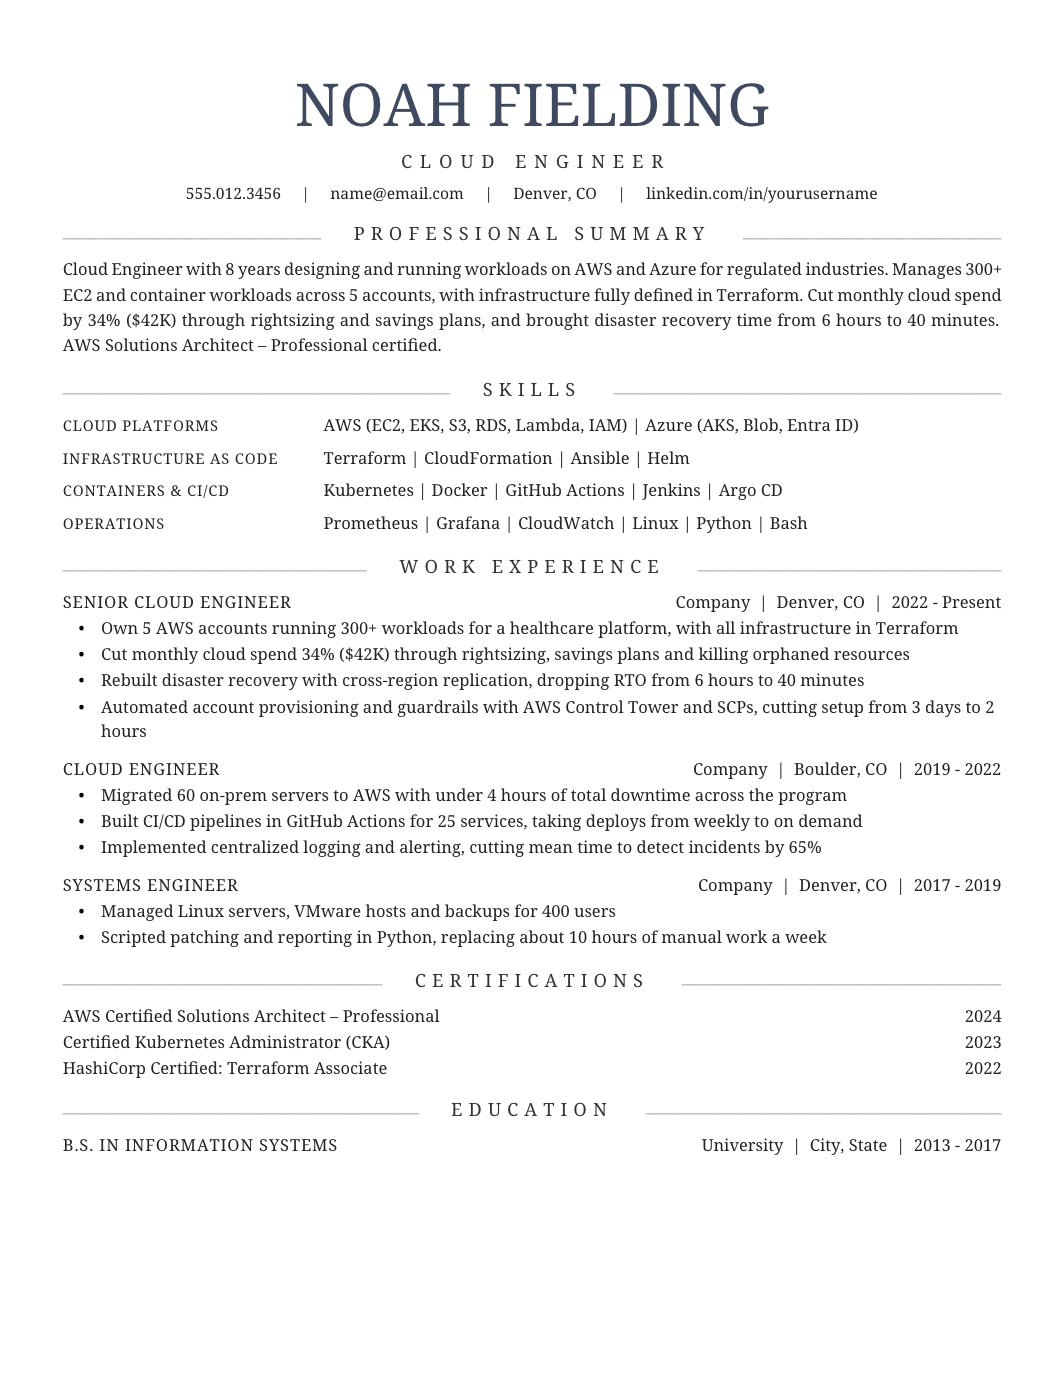
A resume for engineers who build and operate cloud infrastructure.